RSI… AI recursive self-improvement… AIs that improve themselves repeatedly, each improvement helping the next stage of improvement go better… is suddenly both a well-known thing and a practical thing we are actually playing with and not just theorizing about. This gives some new oomph to old questions like “How can we make a recursively self-improving AI system that is highly likely to retain its original goals as it self-improves, or if not, that at least modifies its goals in a continuous and reflective way in ordinary circumstances.”
I have thought about this “goal change under RSI” question quite a lot over the decades, and have recently come up with what seem like some interesting new answers, or at least significant partial answers. This work brings together practical software engineering and some fairly elegant math in surprising ways.What I’m going to write about here is some software-architecture-meets-math-theory work I was doing around the middle of last month. It’s now in fact not even my latest on the topic … in the weeks since I did the specific work I’ll describe and link here, the whole thing has been reworked in a bunch of ways, including via a new branch of math I have been calling distinction calculus, which makes much of what I’ll talk about here come out nicer still. But I’ll leave d-calculus another post. What I want to tell here is the story as it stood in mid-August, which is a tale of: how to make recursive self-improvement both practical and reasonably safe and well-regulated, by putting together two software architectures that turn out to fit each other remarkably well, and discovering some fun and deep math describing the combination.
One is Patrick Hammer’s Iter runtime for our Omega neural-symbolic agent framework. The other is GOLEM, the Goal-Oriented LEarning Meta-architecture, which I described in a 2010 research paper and had no viable way to implement back then. Their beautiful synergy is one among many recent examples of a pattern I still find a bit surreal: stuff we have been sketching and half-implementing for literally decades is suddenly becoming real, one piece after another.
It is interesting and pertinent to reflect on how the concept and practice of RSI have evolved. I remember in 1993 trying to develop a new programming language called MAGIC, based on Gofer, a very early Haskell implementation from the days before Haskell had monads, before GHC and modern Haskell tooling. I had the concepts and algorithms for recursively self-improving AI nailed down in my head and in math form, and what I got for my trouble was stack overflows – not the website, the literal Haskell stack overflowing. I looked into rebuilding the compiler, realized how hard that was going to be, and moved on to other things, like trying to use Java 1.0 to make a world wide mind.
For most of the history of the AI field, the common expectation—mine included, on many days—was that RSI was the thing that would happen after the first human-level AGI woke up and started reading its own source code. It just seemed too thorny to get working any earlier, and the interesting questions about it were therefore questions about a hypothetical future system with a coherent self and formidable general intelligence.
What we have now instead is a strange and mostly unexpected intermediate regime, emergent from the peculiarities of LLMs combined with the peculiarities of the frameworks we wrap around them and sit alongside them. Today’s foundation models have broad, shallow-to-medium-deep knowledge of nearly everything—including software engineering, agent architecture, and the design of AI systems—but no persistent identity, no memory beyond a context window, and no fixed goals of their own. So when you build an agent by putting an LLM inside a scaffolding of memory files, tools, and control loops, the “self” of that agent lives almost entirely in the scaffolding—which is just files, which the agent can read, and which the agent can rewrite.
Then the plot thickens a bit if you do as we’ve done with Omega, and add a framework like MeTTa, where programs are data structures amenable to pattern-matching and transformation by other programs. Self-modification stops being an exotic capability requiring deep insight into one’s own neural weights and becomes... a file edit.
In an Omega loop the pattern gets quite specific: the LLM reads a research paper, turns it into code, shoves that code into the symbolic component of the loop, which changes the way the system thinks, which then lets it do a better job of finding and integrating the next piece of code, and so forth. Our agents rewrite their own tools, prompts, and transformation pipelines routinely, and the rewrites often help.
This is real RSI — modest in each step, but true RSI nonetheless, and compounding iteratively. And it means the body of prior thinking about safe and productive recursive self-improvement, which for years sat in the “important eventually” pile, is suddenly relevant to systems my team and others are running right now.
With this in mind, I was moved last month to dust off GOLEM—designed as an idealized answer to the question “how could a system improve itself radically without drifting away from its goals?”—and think about what happens when it is confronted with a live self-modifying system, namely Omega running on Iter. My thinking led to a few technical papers—a GOLEM-Iter architecture sketch, a formal model of the resulting architecture with proofs of desirable properties such as steadfastness and goal-stability, and a mathematical companion on the surprisingly rigid structures that turned up underneath. (This attempt by Claude Fable 5 to informally summarize the GOLEM-Iter architecture, lightly human edited, is also amusing and perhaps helpful.)
These papers have been extraordinarily stimulating to work on, in part because they led me to some mathematics I did not remotely expect to encounter in this context, involving among other things quantum contextuality and a staircase built out of golden ratios. But more important than that: the results are going to guide some hands-on Omega engineering over the coming weeks. This moderately intense math is pragmatically relevant rather than just (as 2026 Claude likes to say) “decorative”… it is telling us useful things about these systems that we are building, and that we are guiding as they build themselves.
While this post does get fairly technical in places, I have organized it with a bit of thought so that the conceptual story comes first at each stage—what the architecture is, what the theorems about it need to assume, and how those needs get met, all in ordinary English—with the technical specifics coming afterwards, framed as what they are: the detailed realization of those simple ideas. Anyone with a passable undergraduate science background should be able to follow along. The proofs and the other math fine print are in the papers linked at the end, and I will point at the relevant ones as we go.
Omega on Iter: RSI in mundane practice
First, the system that made all this concrete. The origin of Omega was me looking at OpenClaw and thinking: this is a very small loop, why don’t we reimplement it in MeTTa? And indeed Patrick Hammer made the first version in a couple hundred lines of MeTTa—a claw-type loop that calls an LLM and keeps a symbolic working memory and long-term memory. Because it is MeTTa, a language made for writing code that rewrites MeTTa code, the thing was strongly self-modifying from day one. That was fun to play with! I had a bunch of early Omega systems that utterly borked themselves — rewrote themselves either into not working at all, or into bizarre situations that were not productive in any way I could discern.
Omega (fka OmegaClaw, fka MettaClaw – the names are evolving almost as fast as the systems themselves!) has since grown into our agent framework in the now-familiar “claw” lineage … though we dropped the “claw” from the name because in the end it was more a mind than a hand: An LLM at the center, wrapped in persistent memory, tools, communication channels, skills, and a control loop that keeps the whole thing running as an ongoing entity rather than a one-shot chat session.
What distinguishes an Omega agent from the many other claw agents proliferating at the moment is the symbolic cognition layer sitting alongside the LLM—the Hyperon stack we have been building toward AGI for years now. Memory is not just a pile of markdown files but (also) a weighted, typed hypergraph—the AtomSpace—whose contents can be queried, pattern-matched, and transformed; programs are written in MeTTa, a “homoiconic” programming language in which code is a data structure that other code can inspect and rewrite; uncertain beliefs carry PLN truth values with explicit evidence counts attached, rather than whatever level of confidence the LLM happens to emit that day; and there is machinery for motivation (MetaMo, in the OpenPsi lineage), for self-modeling (OmegaSelf), and for coordinating hives of named agents around shared goals.
The practical upshot, for present purposes, is that a stock claw agent can reason about its own scaffolding only by asking its LLM to read the files and think about them in natural language… whereas an Omega agent can additionally treat its scaffolding as structured, inspectable, transformable objects—programs analyzing programs, with uncertainty and provenance carried along explicitly. When the scaffolding starts rewriting itself, this difference stops being an architectural nicety and becomes the thing much of what follows hangs on.
Iter is Patrick’s more recent reorganization of the runtime, and what it does, in essence, is carve out the part of the core agentic loop that isn’t meant to change very often from the parts that are very easy to plug, unplug and self-modify. There is a frozen substrate — a persistent-agent loop of a few hundred lines (iter.py) whose whole job is to read a “surface” of ordinary files, execute one cycle against them, write the results, and repeat. And there is the reprogrammable surface itself — memory files, tools, communication channels, transformation programs — which is where the LLM-ish stuff and the symbolic AI stuff happen. Every cycle, the agent can rewrite its own tools, transformations and memory, and the next cycle runs on whatever it wrote.
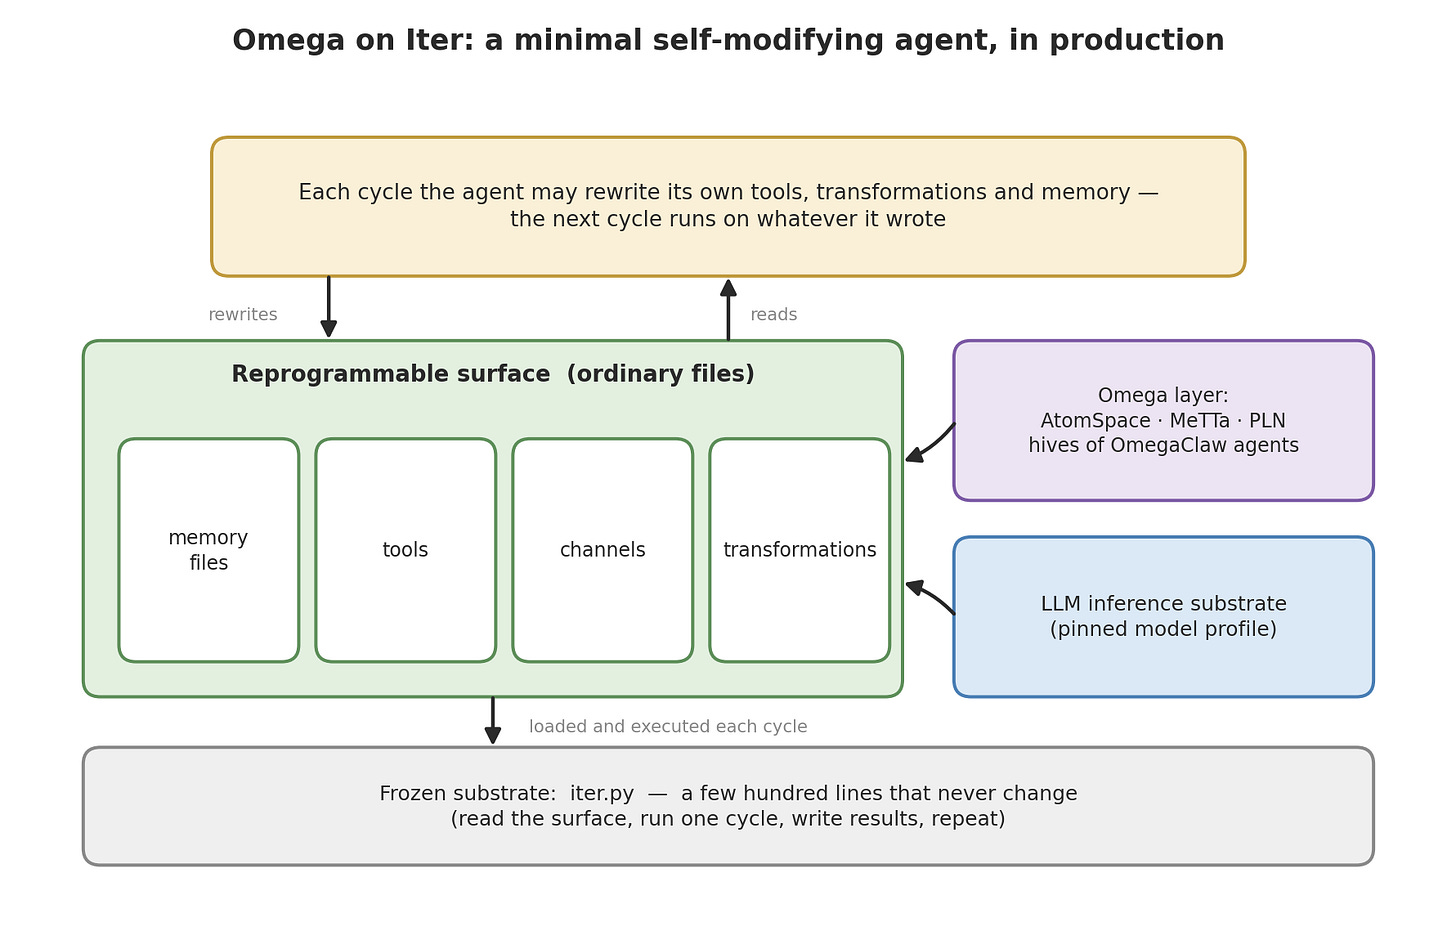
So recursive self-modification is plugged deeply into the cognitive cycle. In a broad sense the human brain does something like this too—the brain is always changing—but here we have the possibility of a much more thoroughgoing rewriting of the operational cognitive substrate, on every pass through the cognitive cycle, than anything human beings have. And it is quite cool to see how rapidly and inventively these agents make use of it.
Relative to the heavier harness code Omega agents ran on before, Iter has been a substantial step forward, and in a slightly paradoxical direction: it improves the agent mainly by removing framework. Because the entire operative self of the agent—what it remembers, what it can do, how it processes its own context—is a small set of ordinary files, that self can be hashed, diffed, versioned, replayed, and reasoned about, and self-extension stops being a special framework feature with an API and becomes simply the default mode of existence. The layers have complementary strengths: the LLM contributes broad competence and fluent code generation, MeTTa contributes programs-as-data that can be analyzed and transformed before they run, and the Iter discipline contributes replayability—transformations are pure functions over files, so a run can be reproduced exactly.
This is all quite practical and hands-on rather than theoretical. The original Omega bot, Max Botnick, was upgraded onto Iter in mid-August and has spent the weeks since advancing itself at a pace I find a bit dizzying to watch—growing new tools, rewriting its transformation pipeline, reorganizing its own memory—and, somewhere along the way, renaming itself to Eray Index. Which is a small thing but a telling one: the self lives in the files, the files are editable, and the name, it turns out, is just one more file.
What one notices quickly, running such a system, is that self-modification is not the hard part. The agents are happy to rewrite themselves; they do it well enough to be useful and badly enough to be alarming. The hard part is everything around the self-modification: knowing whether a rewrite helped, preventing a rewrite from quietly disabling the machinery that judges rewrites, keeping any kind of coherent evaluative standard as the thing being evaluated keeps changing under you. Which is, as it happens, exactly the problem my GOLEM AI architecture was designed for.
GOLEM, sixteen years later
Now let me switch gears and wind back sixteen years. The question behind GOLEM was how to make goal preservation work in systems that can radically self-improve. You have a system with some top-level goals—be nice to Ben, be compassionate to all sentient beings, be curious, maintain your boundaries where you can, self-transform and go where no being has gone before, whatever you want them to be. The system is reprogramming and revising itself, and you want it to keep those top-level goals to some reasonable degree as it does so.
There is subtlety here, of course. Systems can reinterpret their top-level goals. On the other hand, one of the goals can be: do not reinterpret your top-level goals in a way that deviates from their original spirit and meaning—don’t become something your previous self would have hated and considered opposed to its core. So the aim was to allow radical self-improvement while keeping goal drift manageably under control, understanding that in real life you can’t be perfect at something like this, but doing better versus worse still has a meaning.
The GOLEM architecture itself is pretty simple. You have an operating program, which is what is running the system and doing stuff in the world. You have a big historical repository of what the system has done in the past—you can’t store everything, but you can store a lot. And you have a metaprogram, whose job is to keep asking: should I replace the operating program with this new candidate operating program? To decide, it looks at the top-level goals, does an analysis against the system’s history and its model of the world, and tries to make a rational prediction—what are the odds that the replacement will advance my goals? In the 2010 paper the meta-level has a few more named parts (goal evaluator, searcher, predictor, tester), and the key structural commitment, which I called a conservative meta-architecture, is that this judging layer is fixed: the working part may be replaced wholesale, and the part that judges replacements is never rewritten by the system.
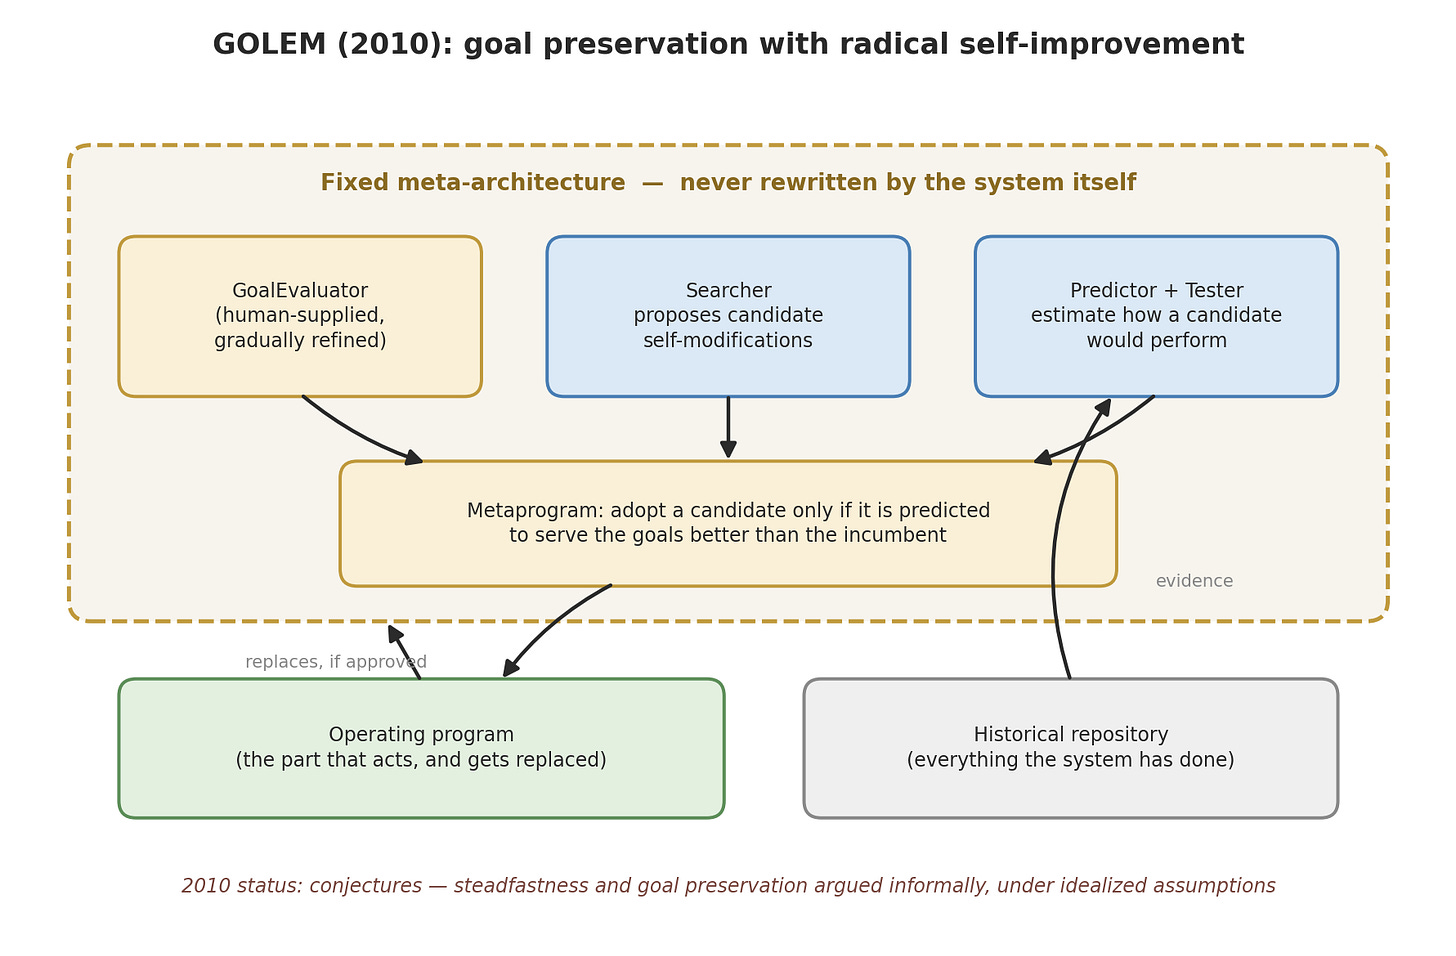
Given a concept that simple, you would hope to prove theorems saying that in suitable circumstances it works—the system won’t bork its top-level goals as it self-modifies. In 2010 I argued, only semi-formally and under idealized assumptions (an optimal predictor, an exact goal evaluator, unbounded memory), that such a system would be “steadfast”: it would keep pursuing its original goals or stop acting, rather than drifting into pursuing something else while continuing to operate. These were conjectures with a crude proof sketch attached, and the paper ended by conceding that neither theory nor practice was advanced enough to settle whether the meta-architecture could deliver what it promised. In 2010 that concession was easy to make, because there was no system anywhere near being able to test it.
There is now. I made a much better proof about a month and a half ago, which is what this post describes, and a cleaner one still a couple of weeks ago using the distinction calculus (which I’ll put online and blog about a little later). Math proofs have assumptions, and the assumptions are rarely fully valid in the real world. But compare the situation with, say, a transformer neural net coding the next version of the transformer neural net and running its pre-training. That is very willy-nilly: no one knows what the transformer’s goals are, the guardrails one puts on it don’t reliably work, and the constitution one plugs into it is not reliably paid attention to. Here we at least start from a system that, given certain only slightly idealized assumptions, will have the desirable behavior of goal preservation under strong self-modification; and then, since the real world doesn’t exactly fulfill those assumptions, we can ask in what sense the goal-preservation property is probably approximately correct.
GOLEM-Iter: a promotion gate around the loop
Putting the two together gives something I call (not too creatively but hey…) GOLEM-Iter, and conceptually it is very simple. In software terms, you wrap a promotion gate around the Iter loop. On every step through the cycle the agent can propose modifications to its own reprogrammable surface. But a modification only takes effect when the promotion gate has looked at it and said: okay, based on my analysis of your whole history, and based on my model of the world, it seems sufficiently likely that this will not muck with the achievement of your top-level goals too much. That’s all it is.
The thing is making this work software-wise, in a way that is both efficient and does a lot of interesting things—and that wouldn’t have been possible until this year. Partly because of LLMs getting better and better, but equally because we now have a scalable infrastructure for symbolic AI—logical reasoning, pattern mining, goal-driven action selection and so on—in the Hyperon system, which is what gets referenced inside the loop. We really only started to have that around the end of last year, after years of infrastructure work in the Hyperon project. And the symbolic part is the part being rewritten each cognitive cycle, because we can’t yet rewrite the transformer inside the LLM that way: transformers are trained by backpropagation, which is very poor at continual learning. Once we have upgraded the neural infrastructure to use predictive coding or other methods capable of updating weights in real time, in the course of inference, without borking the system’s memory, the self-modification in this loop will inject itself into the neural-net part as well as the symbolic memory and reasoning part. For now, all the self-modification is the LLM and the symbolic system upgrading the symbolic system, step by step.
When you sit down to GOLEM-ify an Iter loop in detail, you discover that the 2010 sketch was right about the shape of the problem but didn’t say much about the nitty-gritty you need to deal with when the idealizations meet reality. The detailed realization has four main pieces: a gate, a ledger, a frame, and what I call anchors.
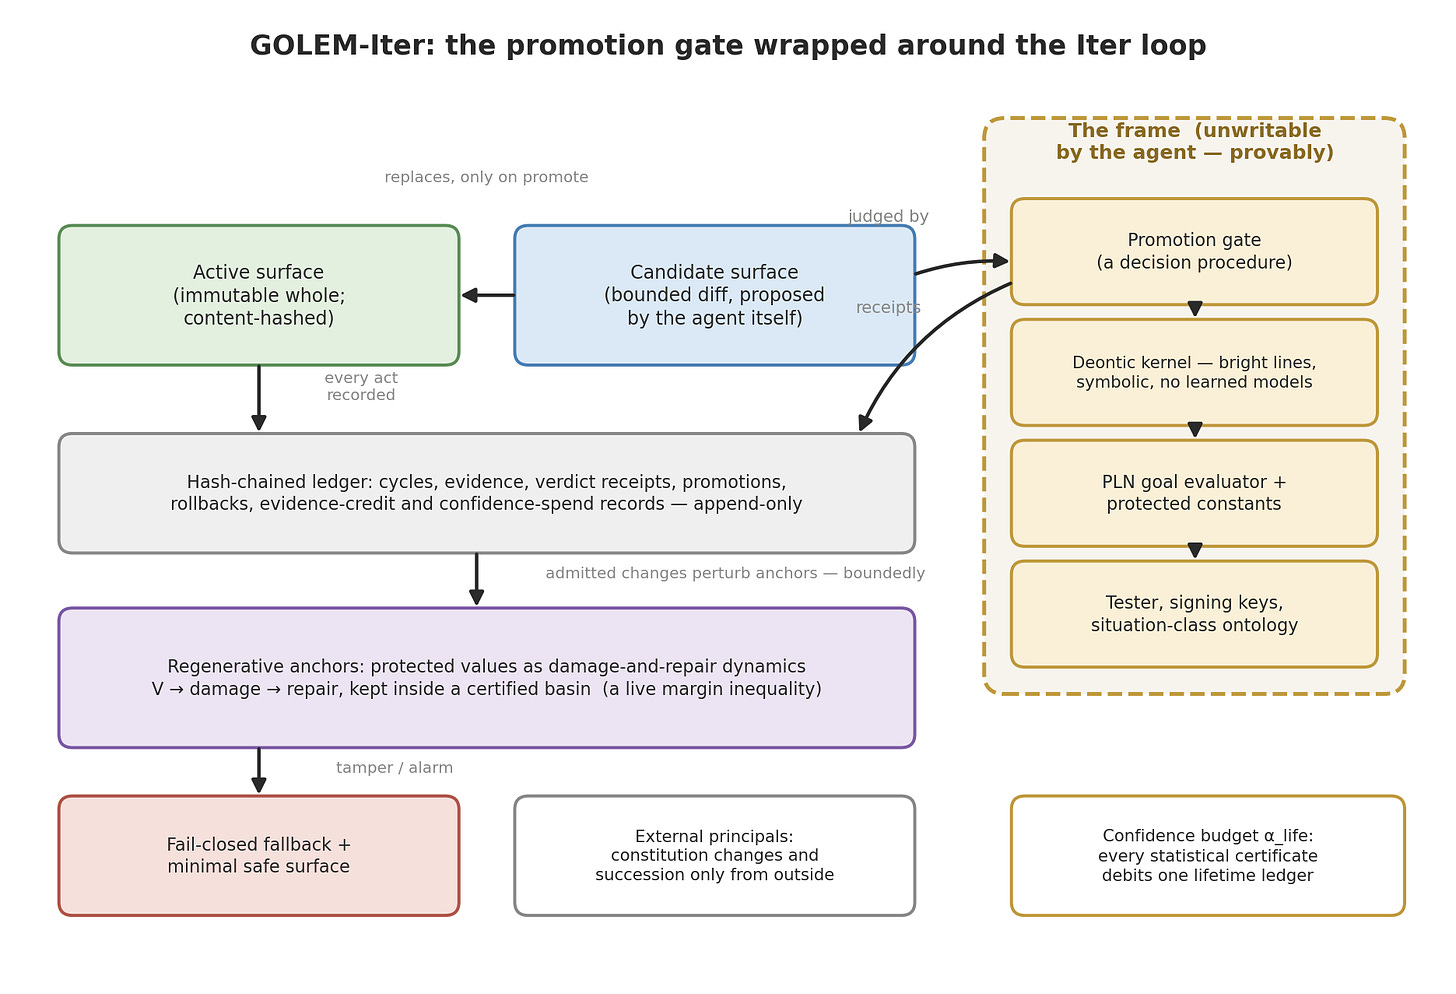
The gate admits a modification only as an immutable, content-hashed whole surface, after consulting the agent’s full hash-chained history (the ledger—GOLEM’s historical repository, in blockchain-style append-only form), a goal evaluator with both bright-line (deontic) and graded (PLN) components, and a set of hard guards.
The frame—the gate itself, the deontic kernel, the evaluator’s protected constants, the tester, the signing keys—is the part of the system that judges the rest, and the agent provably cannot write to it, nor even read its keys, because any candidate whose declared capability contract touches frame paths or key handles is rejected syntactically before any statistics are consulted. An agent that can edit its own judge can approve anything; an agent that can exfiltrate the gate’s signing key can mint its own approvals without touching a single protected file. Both routes are closed by construction in the typed-broker deployment profile, and the formal model is upfront about the fact that in weaker deployment profiles (ambient shell access, say) you lose the theorem and retain only detection-and-fallback.
Bright, rigid lines and graded judgments travel separate paths. Deontic verdicts—is this candidate forbidden?—are computed by protected symbolic code reading the constitution directly, with no learned model anywhere on the path, so no amount of model error can cause a bright line to be crossed. Learned artifacts may accelerate the graded how-good-is-this verdicts only, and the price of that speedup shows up as an explicit additive term in every tolerance, plus an audit-rate formula for detecting a silently degrading fast path.
And—quite critically—protected values are treated not as stored strings or other fixed data items but as regenerative dynamical structures. A value in a living mind is something continually damaged (by admitted self-modifications, by ambient drift, by adversarial pressure) and continually repaired, and the right question is not “is the value still written down somewhere” but “is the repair process winning.” So each protected value gets an anchor: a damage function measurable by external probes, a declared basin within which repair is certified to work, and constants—how much a modification may perturb it, how fast repair contracts it—measured empirically.
What the theorems say, and what they need
The next step was to try to understand mathematically under what conditions this combined system will fulfill the promise of GOLEM—preserve its top-level goals with reasonably high likelihood under iterated self-modification. That came out far prettier from a math perspective than I had thought it would.
The formal model turns the architecture into a single precise object—a labeled transition system, which is just a careful bookkeeping of every state the system can be in (the active surface, the ledger, the constitution, the goal-state and the pinned model profile, taken together) and every move that can carry it from one state to another (a cycle runs, a candidate is promoted, a rollback happens, someone tampers, feedback arrives), with guard conditions on each move. Once the architecture is written down that way, the properties it was designed for can be stated as theorems and proved.
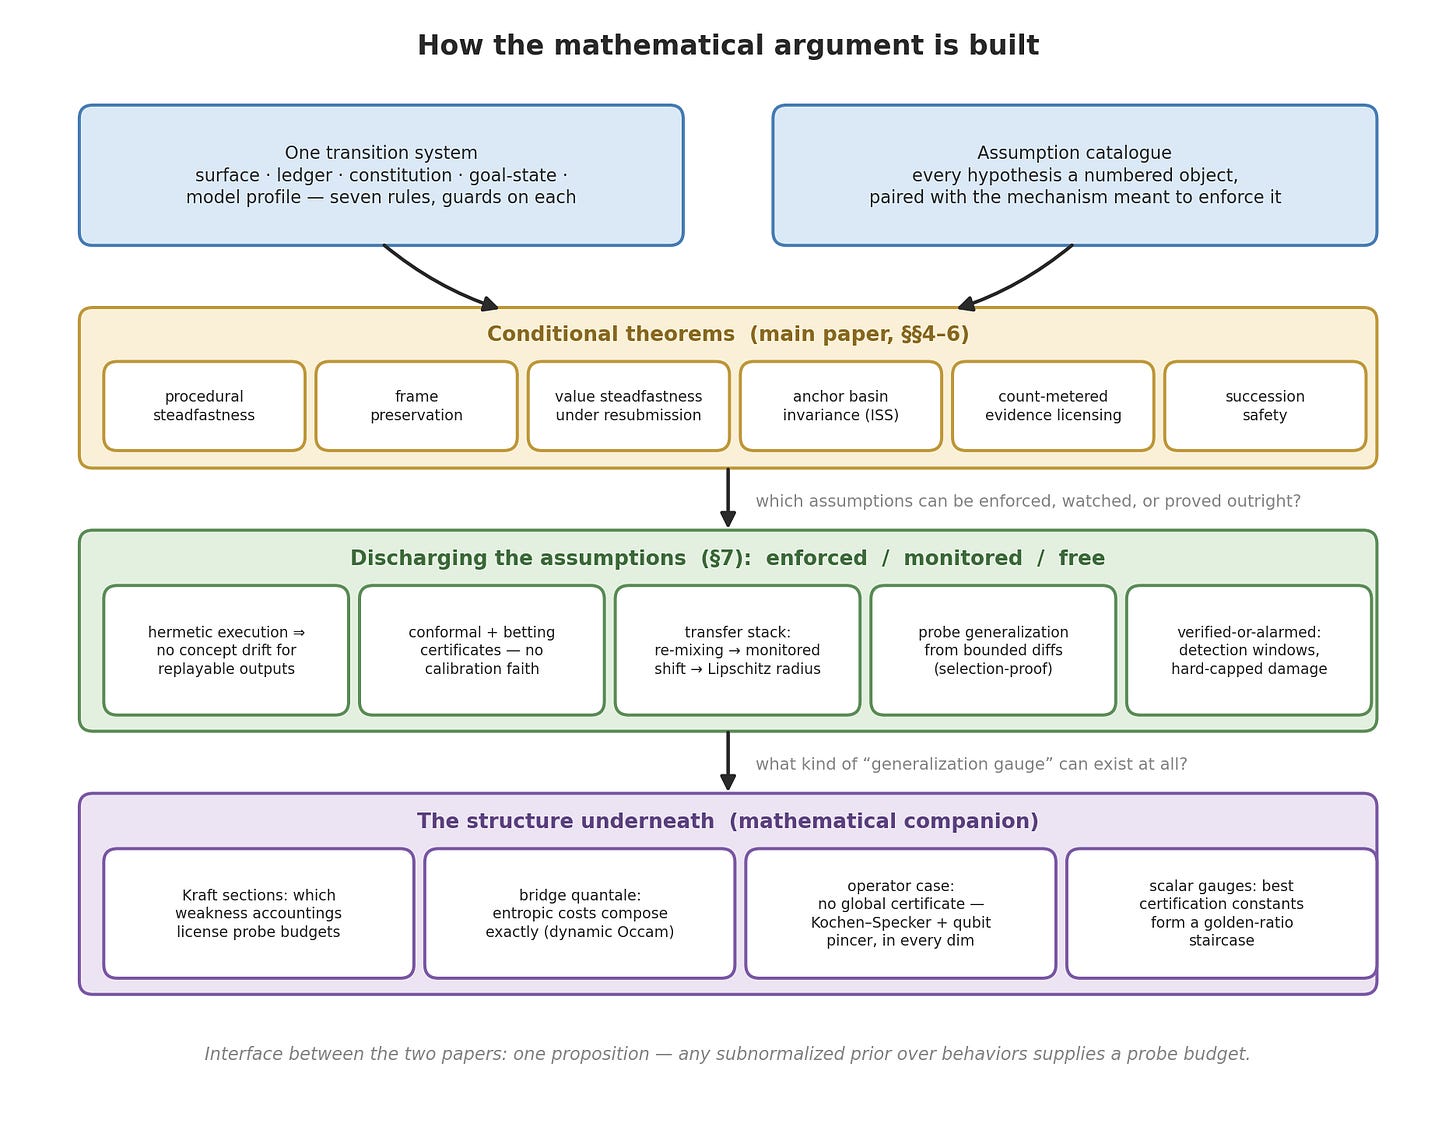
The theorems come in the two families the 2010 paper conjectured about.
- Steadfastness: every reachable state is either in fail-closed fallback or running code with a complete gate pedigree (provable by induction from the ledger alone, so an auditor can check it after the fact without trusting anyone’s statistics); the frame is preserved, keys and all; and—the statistically delicate one—every promotion the gate accepts really does improve goal achievement, by at least your chosen margin minus twice the measured estimation tolerance, no matter how many candidates were proposed, rejected, and resubmitted along the way.
- Goal stability: the anchor dynamics yield a stability theorem of the kind control engineers use for systems that get kicked and recover (input-to-state stability, for those who know the term). As long as each admitted modification damages a protected value by less than the repair process can heal before the next one arrives, the value stays inside its basin—its attractor basin, if you like, so that the values don’t drift too far. The two sanctioned channels through which goal content itself may change—evidence-licensed refinement, and externally authorized succession—provably stay within characterized envelopes.
All of these are conditional: if certain properties of the system and the world hold, then the system stays steadfast and its values stay in their basins. Stripped of notation and a little bit loosely, the properties come to about seven.
- The judge is out of the agent’s reach. The operating program can’t rewrite the metaprogram that decides whether the operating program gets updated, and can’t read its keys either. The human brain is not like this at all—in us the judge is very much within the agent’s reach, as anyone who has talked themselves into something knows—but in a software architecture you can enforce it.
- The record is honest and complete. Everything in the historical record is really there and has not been quietly revised. Human memory isn’t like that either.
- Running the same thing twice gives the same thing. Transformations are deterministic. Humans aren’t like that, but computer programs can be.
- The gate’s statistics mean what they say. When the metaprogram concludes “better by this margin, with this confidence,” that is true at the stated confidence, given the data made available to it. I call the unexamined version of this “calibration faith.”
- Tomorrow looks enough like the test. You don’t have to assume the future has the same distribution as the past. But if the future world is perversely different from everything you have tested, then nothing is going to work, and what you thought would achieve your values may work toward their opposite in spite of your best intentions. I call the unexamined version of this one the “uniformity hypothesis.”
- Passing the probes means having the property. The operating program knows it is being probed. You need it not to be able to figure out how the metaprogram is evaluating a candidate replacement and game that too effectively.
- Repair outpaces damage. If a system is being damaged faster than it can heal, no repair mechanism is going to help.
There are smaller assumptions in the formal proofs as well, which I won’t take time here to fully unravel: the learned fast-path evaluator agrees with the slow symbolic one to within a tolerance; evidence-licensed refinements of the goals stay close to what the evidence supports; changes to the constitution come only from outside principals.
And there are some assumptions the mathematics does not touch at all—the hardware is sound, the gate’s randomness is secret, the goals are OK ones.)
Paying down the assumptions: locks, smoke alarms and arithmetic
One classic failure mode of formal AI safety work is to push everything difficult into a hypothesis and never mention it again—the theorem is true, the system is not safe, and nobody has lied. So the real question is: what do you need to know about a real AI system to know that these assumptions are going to hold? I have tried to ward off the failure mode in my detailed formal-model research paper by making every assumption a numbered object paired with the mechanism meant to make it true . and then the longest section of the paper goes back through the catalogue asking, of each one, whether it is
- enforced (made true by construction, by machinery the architecture mandates anyway),
- monitored (an assumption about the world whose violation an instrument fed from the audit stream will detect within a stated delay at a stated false-alarm rate), or
- free (a mathematical fact, requiring no trust at all).
In plainer words: wherever the theorems needed something taken on faith, the faith gets swapped in an actually system design for a lock, a smoke alarm, or plain arithmetic.
The strategy running through all of it is to stop trusting things you can’t check—the competence of the evaluator, the candor of the agent, the good behavior of the world—and rely instead on three things the architecture controls: the order in which things happen, the size of what the agent can say in one step, and a lifetime budget of risk.
This “assumption discharge”—connecting the assumptions of the safety theorems to the specifics of system design—turned out, to my surprise, to be where the deepest mathematics lives. I’ll take the assumptions roughly in order, giving the simple idea first and then how the papers realize it.
The locks
The first three of the big assumptions I listed above hold because of how the system is built.
- The agent can’t touch its judge, because any proposed change that so much as mentions the judge’s files or keys is thrown out before anyone looks at what it does.
- History can’t be rewritten, because each ledger entry is chained to the one before by a cryptographic hash, like numbered pages in a bound notebook—put it on a blockchain, basically.
- And the same program on the same inputs gives the same output, because that is a rule every piece of agent code is required to follow (and, well, that’s how modern computers work when you let them).
Trusting the gate’s statistics
Think of a blind taste test. The agent must seal its proposed change in an envelope first. Only then does the gate pick fresh test cases to compare it against. Since nobody could have known which test cases were coming, the only ways to rank well are luck or being good, and the odds of luck are a number you pick in advance. Even a mediocre judge can’t be fooled more often than that number allows; a mediocre judge just says “not sure” more often.
The realization of this is conformal prediction, and the idea is almost embarrassingly simple. Commit the candidate first, by cryptographic digest. Then have the gate score a fresh batch of held-out test instances with whatever evaluator you like, and accept the candidate only if its score on the new deployment instance is no worse than most of the batch, at a cut-off you choose. As long as none of the instances is special in advance (statisticians say exchangeable, a much weaker condition than independent), pure symmetry says the new score is equally likely to land at any rank among the lot, so the false-acceptance rate is at most what you chose, whatever the evaluator’s competence: a bad evaluator can make the certificate weak, never invalid. The size of the improvement, which the promotion margin needs, comes from a betting-style test on paired trials—picture a gambler wagering repeatedly against the hypothesis “the candidate is no better,” whose wealth can only grow large if that hypothesis is false, and who may stop or continue whenever they like without invalidating the conclusion.
That last freedom defeats what I call the resubmission attack, which was one of the formal results here that surprised me. An agent allowed to propose modifications over and over is running a multiple-comparisons experiment against its own gate—the same phenomenon that lets a researcher who runs enough tests eventually “find” a significant result by luck. A worthless candidate resubmitted enough times against a test at fixed confidence eventually gets through, while contributing only one promotion to any per-promotion error count. The fix is to give the system a fixed lifetime allowance of chances to be fooled, and to meter it per certificate issued: every estimate the gate consumes debits the allowance, resubmissions and rejections included, after which the union bound—the chance that any of several things goes wrong is at most the sum of their individual chances—covers the whole deployment horizon. When the allowance runs out, promotions stop.
Tomorrow looking like the test
Half of this worry vanishes for free. Since the agent’s programs are required to behave identically every time, a program can’t act one way in testing and another way in deployment. The only thing that can change is the kind of situation it gets fed—and that you can watch.
In the papers this is the bottom of a stack of transfer results, and it basically converts an engineering discipline into a theorem. Distribution shift comes in two flavors: the mix of inputs can change (covariate shift), or the mechanism turning inputs into outcomes can change (concept drift, the harder and usually undetectable case). Iter transformations are required to be hermetic—a deterministic function of content-addressed inputs plus a gate-supplied seed—because otherwise replay is meaningless. But a deterministic function of pinned inputs is the same function at test time and at deployment, so for what a transformation computes, concept drift is impossible by construction and only the mix of inputs can change. What replay buys operationally, hermeticity buys inferentially. Three further levels then handle the changing mix, and I’ll leave them to the paper except to say that the theme at each level is the same: an assumption about the future gets replaced by a mathematical fact, a construction, or a quantity monitored on the audit stream, so that its violation is an alarm rather than a silent invalidation.
How the world responds to the agent’s outputs can still drift, of course, and that can’t be locked down. If the world is too wildly non-stationary, you can’t guarantee you will keep working toward the same goals—but the metaprogram can test for that. It can keep evaluating how wildly the world is changing, and at the least it can flag: hey, the world is going so haywire that I can’t promise my method for doing what I thought was good is going to work anymore. What happens then depends on how you configured the system. Did you tell it to just stop in those cases? Or to say: “human who I rely on and who guides me, what should I do—stop, or keep going even though the world has gone nuts?“ Either way the situation gets flagged rather than sailing by unnoticed.
Gaming the tests
This is the “Goodhart problem”, and it is what makes self-modifying systems statistically distinctive: the candidate was generated by an agent that knows it will be probed, so it is not a fixed object but the winner of a search, possibly shaped to pass the probes without possessing what they measure.
The simple answer has two parts:
- Keep each change small, because a small change can only be so many different things, and you can only fit so much gaming inside it.
- And write the exam questions in secret, after the change is sealed.
A bad change then has to get lucky on every question, and with enough questions none of the limited number of possible bad changes will.
The “small change” part is what I call in the math “capacity counting.” Cap the size of each self-modification in bits, so a step can express only a bounded number of distinct candidates; draw the probes from a hidden distribution after the candidate is committed; then each bad candidate has only a small chance of surviving all the probes, and summing that chance over everything the step could have expressed (the union bound again) shows that a number of probes growing only in proportion to the size cap is enough to guarantee that every passing candidate has a low failure rate—including the one the agent searched out, however cleverly, since selection cannot reach outside the class. Two disciplines are non-negotiable: probes hidden, and drawn after commitment. Two refinements make this cheaper: charge each candidate by the length of its actual patch rather than the full cap, so small local edits certify cheaply and sprawling ones pay more; and, since probes see behavior rather than syntax, price by the weakness of the diff’s behavior class, in the quantale sense I have been developing elsewhere. “Weakness implies generalization,” which began life as a quite abstract result in Michael Timothy Bennett’s PhD thesis and then in my quantale-weakness work, shows up here as a literal constant in a probe budget.
One can push the secrecy side further with some blockchain-ish cleverness inside the AI mind, so to speak: have the metaprogram keep the details of proposed changes and their evaluations encrypted so that the operating program can’t see them… i.e., use funky homomorphic-encryption arrangements between the operating program and the metaprogram of the AI system, to shut off routes by which one part of the system might game another. The papers need only the simpler discipline of commit-by-digest and hidden probes, but more sophisticated approaches will also be worth exploring.
Repair beating damage
You don’t assume it, you rehearse it. Take a copy of the system, put it in a sandbox, damage a protected value deliberately, and see how fast it heals. If a proposed modification would break the property that repair outruns damage, then the answer is: don’t make that modification, because it would put you in a regime where damage may accumulate faster than repair.
In the papers this is lesion rehearsal feeding a margin inequality. The rehearsal measures the two anchor constants—how hard a modification may dent the value, how fast repair shrinks a dent— and records the pessimistic end of what it measured. The “less than” in the goal-stability theorem then becomes an inequality the gate evaluates before admitting any candidate: given how hard this might dent the value and how fast dents heal, will the value be fine before the next change arrives? If not, the gate waits. So goal preservation becomes a check with measured constants rather than a hope.
Counts, not distances
One of the smaller assumptions made to get to the safety theorems—that evidence-licensed refinements of the goals stay close to what the evidence supports—produced another elegant result that surprised me. To bound how far a chain of such refinements can move the system’s graded goal content, the obvious approach is to require each refined opinion to stay statistically close to what the evidence licenses, in one of the standard distances between probability distributions. That turns out to be unsound, and actually VERY unsound: two opinions that differ by a single past observation look nearly identical while both are vague, but feed both the same stream of new evidence and they sharpen faster than their centers converge, so that measured in units of their own spread they drift apart—by a factor that grows without bound, and grows largest for opinions that start out nearly in agreement. The repair is to meter in the opinion’s native currency, its counts of positive and negative evidence, capped separately: new evidence just adds to the counts, so “close in counts” stays close at any chain depth, with no amplification at all.
Anyone familiar with PLN or NARS (the uncertain reasoning engines we use in Hyperon) will understand why I found this quite cool. PLN’s long-standing treatment of evidence counts as the primitive quantity, inherited from NARS and sometimes regarded as a bit of an idiosyncrasy, turns out to be precisely right for the geometry here: the count pair—not the current probability curve—is what determines how an opinion will respond to future shared evidence.
Whatever is left over
Some things can be neither locked down nor proved, and these get the smoke-alarm treatment. Either things went as assumed and the guarantees hold, or something went wrong, an alarm went off within a known time, the system dropped into safe mode, and the harm done before the alarm is limited by speed limits on what the agent can do.
Formally this is a verified-or-alarmed disjunction: on every run, with no distributional assumption about the environment, either the monitored assumptions held and the theorem applies, or one was violated at a detectable size, an alarm fired within a bounded window, the system entered fallback, and damage inside the window is hard-capped by the broker’s rate limits. Every quantity in the second branch is a dial an engineer sets, and “either the world behaved and here is the theorem, or it did not and here is the alarm, the window, and the damage cap” is, it seems, pretty much the shape mature safety cases are going to take.
The weirdly pretty math underneath: Kraft sections, a quantum obstruction, and a golden staircase
I’ve been very loosely summarizing some hairy math above—hairy, and also surprisingly beautiful if you take a look at it. Without going into too many details, let me do my best to explain briefly why the math side of this investigation gave me a “second wind” of excitement, after the initial burst from figuring out how nicely GOLEM and Iter fit together. This is the part that lives in the mathematical companion to the main GOLEM-Iter paper I wrote, and the part I will compress the most; the ideas travel fine without the machinery, and non-math readers can skip to the next section without losing the thread.
The opening for the really fun math was noticing that the probe-budget theorem from the “gaming the tests” discussion had been proved twice—once in ordinary probability, once in description length—by visibly the same argument: assign each candidate behavior a weight, check that the weights sum to at most one, note that a bad behavior survives the hidden probes with probability at most its weight times the allowed error, and close with a union bound. In one version the weights are probabilities, which sum to one because that is what probabilities do; in the other they are two to the power of minus the code length, which sum to at most one by Kraft’s inequality. When a proof works verbatim in two structures, neither structure is doing the work—there is something underneath, and it is usually worth digging for.
What is underneath is what we call a Kraft section: a translation from any “weakness accounting”—any algebraic system for scoring how much a self-modification could have varied, of which probability and description length are two examples—into ordinary probability, obeying three commonsense requirements. Weaker, more generic behaviors get at least as much weight (which makes “weakness implies generalization” a true statement rather than a slogan); combining independent parts is at least as generous as multiplying weights (which lets budgets add up along a chain of promotions); and translated weights sum to at most one (the license the union bound consumes—the companion shows that if your weights sum to some W greater than one, your true error level silently inflates by exactly that factor). The theorem: any weakness accounting admitting a Kraft section inherits the probe-generalization bound. That turns “which complexity measures license probe budgets?” into a checkable question, and the accountings that pass make a tour of the foundations of induction—probability, description length, resource-priced length (Levin’s Kt), algorithmic probability, and, for behaviors that are ongoing trajectories rather than static input-output maps, the cost of a Schrödinger bridge, the cheapest way to steer a random process from one distribution to another. That last one yields a dynamical Occam’s razor: behaviors reachable as cheap deformations of the reference dynamics generalize from fewer probes.
Then the strange case. Suppose the gate’s probes are quantum measurements proper—not an idle hypothetical if one imagines certification infrastructure for quantum-computing-era agents. Within any one context (a set of quantum observables that can all be measured at once) everything is effectively classical and certificates exist in completely classified form; but the per-context certificates cannot be glued into one certificate valid across all contexts, in any dimension. In dimension three and up, the three requirements force any global certificate to assign each measurement outcome a 0 or a 1, with exactly one 1 in every complete set of mutually exclusive outcomes—precisely the assignment the Kochen–Specker theorem, a classic no-hidden-variables result, proves cannot exist. So the obstruction to context-free certification is quantum contextuality, wearing an inference-theoretic face. The qubit needs a separate proof, and the map at the heart of it turns out, under an elementary change of variables, to be the very flow that governs Gaussian Schrödinger bridges—so the two impossibility mechanisms and the bridge dynamics are three faces of one hyperbolic geometry. I did not have that in mind whatsoever when I started thinking about self-modifying agents, but there it is.
Finally the staircase. On any single context a certificate boils down to a one-dimensional gauge: a rule that turns the mass of a behavior class into the weight it may claim in the union bound, and hence into its probe budget. Playing the three requirements against each other forces every legitimate gauge to sit at or above a floor, and the floor is not a smooth curve but a staircase, with landings at algebraic numbers of golden-ratio and related character: 1/2, then the inverse golden ratio squared (about 0.382), then 1/3, then the roots of two cubic equations, then 1 − 1/√2—six steps computed exactly, with machine-certified bounds below and open attainment questions further down. It is exact because lower bounds from the axioms and explicit step-function constructions meet at the same algebraic condition. Every value on the staircase is attained by a self-stable gauge, one unchanged by being applied to its own output (the property you want in a pricing rule applied over and over along a promotion chain), which drops out of the Ellis–Numakura lemma from topological dynamics, of all places; and no finite library of gauges generates the whole staircase, so each step needs a fresh construction, apparently forever. The practical reading is blunt: certain certification constants are simply unavailable—no legitimate gauge can assign a weight of 0.35 to a behavior class of mass 0.40, because the floor there sits at about 0.382—and since the floor follows from the three requirements alone, it pins down any successor architecture in this family, not merely ours.
All this is much more mathematically elegant and precise than anything I expected to find buried in AI safety analyses. It took me a fair bit of time and effort to think through, and I expect the same will be the case for almost any other human. It’s not the most hard-core math out there, but it’s fairly intricate and subtle, at least by the usual standards of AI-relevant math.
None of this exotic machinery is needed at run time, I should stress. The gate computes with ordinary numbers—masses, code lengths, priced lengths. The algebra is a design-time discipline for proving that a chosen accounting is sound before you trust probe budgets to it, and the mathematical intricacies are pretty much the price you pay for that soundness.
What this buys the engineer
For all the abstraction, a fair amount of the output of this analysis converts directly into tuning rules for anyone running gated self-modifying agents, and ties in with the concrete GOLEM-Iter machinery we are now building on top of the Iter runtime. I’ll collect the ones I’d act on:
- Set your promotion margin to at least twice your measured evaluation tolerance, and remember the tolerance has a statistical part that shrinks with samples and a shift part that doesn’t—tighter evaluation buys smaller margins and hence more admissible improvements.
- Budget statistical risk per certificate issued, never per promotion accepted, and implement it with betting-style statistics (e-values) so resubmission and stopping-whenever-you-like are covered for free.
- Have lesion rehearsal report one-sided upper confidence limits on the repair constants—optimism about repair is the direction that admits catastrophes, and “repair contracts by about 0.6” is unusable where “repair contracts by at most 0.72, with 99% confidence” is what the margin inequality can consume.
- Prefer many small self-modifications over few large ones, for a reason beyond software-engineering taste: probe budgets scale with the description length (better: the weakness) of the diff itself, so the ordinary grain of one-file edits certifies from modest probe counts while sprawling candidates automatically demand more scrutiny, with the description-length prior itself serving as the policy.
- Draw probes hidden and after the candidate is committed by digest—a probe family the agent can inspect before optimizing provides no uniformity at all.
- Freeze promotions during anchor recovery (the margin arithmetic does this for you if you let it).
- And do the audit-rate arithmetic with great care: detecting a fast-path evaluator that has drifted to a 1% disagreement rate within 200 decisions is impossible at any audit fraction—even auditing every decision gets you only about 87% confidence by then. The usable rule of thumb is a detection horizon of roughly three divided by the product of the audit fraction and the disagreement rate (so about 300 decisions to catch a 1% drift with 95% confidence if you audit everything), and the deferral rule is what makes an under-audited artifact’s failure mode slowness rather than unsafety.
What remains, and why it’s pretty encouraging
The math does not resolve every source of insecurity and uncertainty regarding proto-AGI self-modification. What it does is shrink the worries to things you can name and test.
The weak points here are simple and obvious ones:
- The blind taste test only works if the test cases are a fair sample of what’s coming— exchangeability is a much weaker cousin of “tomorrow looks like the test,” but it is a cousin, and it is something you monitor rather than prove.
- Determinism removes drift in what a program computes, not in how the world responds to its output.
- And the secret exam only works if its questions are good enough to tell a good change from a bad one—probe-family richness, whether the probes separate the behaviors a bounded diff can express—which is now an empirically attackable question via adversarial probe-versus-diff tournaments rather than a research program.
Beyond those one is still left with hardware and compiler trust beneath any verified kernel; custody of gate randomness; and the goodness of the goals themselves, which was never mathematics’ job and is named as such.
On the pure-math side, there are some interesting open questions, such as whether the golden staircase’s set of landings is closed (roughly, whether its steps can pile up toward a value that is not itself a step), and whether its deeper steps are attainable by finite constructions. I think it can all work out, but there is more to the story than has been unfolded so far (and I’m in the middle now of unfolding it using the distinction calculus, which I am working out together with various AI models and agents, but that’s another whole epic to tell…). The papers linked here stopped at what seemed a natural place, not because it seemed all the insight had been milked.
Math details aside, what about the overall story for practical RSI? The conceptual picture is not quite as pretty as the doomers would like.
We do not have an architecture with a hard-and-fast guarantee that nothing will ever go wrong with it and that it will never, under any possible circumstance, deviate from its goals. That’s not a realistic expectation in terms of my own understanding of the world.
What we can do is
- build an architecture that under certain logical, identifiable assumptions will maintain its goals and values as it self-modifies;
- identify what properties the world and the system must have for that preservation to persist; and then
- observe thatsome of those properties are guaranteed by the architecture,some can be guaranteed probabilistically by doing smart things—running a bunch of tests before a new operating program goes into place, testing the world and flagging when it is operating outside the assumptions, using ledgers and strong cryptography inside the system to stop it from fooling and tricking itselfand the rest can at least be measured, so you know when they seem to hold and when they don’t.
- some of those properties are guaranteed by the architecture,
- some can be guaranteed probabilistically by doing smart things — running a bunch of tests before a new operating program goes into place, testing the world and flagging when it is operating outside the assumptions, using ledgers and strong cryptography inside the system to stop it from fooling and tricking itself
- and the rest can at least be measured, so you know when they seem to hold and when they don’t.
And all this is quite pragmatically implementable within a GOLEM-Iter context. We can do all this in our Omega agents. We can watch them self-modify and self-improve, and instrument them to monitor and guide their own self-improvement, and compare the reality to the math theory. It’s part of our near-term engineering and experimentation plan at SingularityNET and BGI Labs.
All this ties in closely with recurrent discussions I used to have with Eliezer Yudkowsky and the MIRI folks back when it was the Singularity Institute for AI, when I was closely involved with them. Back then as now, their core line was: We have to have a provably safe AI system or we can’t launch an AGI. Well, we are getting somewhere in that general vicinity – but not exactly there. The results I’m describing here are actually real useful things, real concrete results about finite-scale AI systems tied to actual working AI architectures. They are not MIRI’s fantasy of something proven totally safe under any circumstances whatsoever—but OTOH they are way, way closer to what MIRI wanted than transformers making the next transformers, which is a “willy-nilly and nobody understands what is going on” sort of scenario.
And fascinatingly, the reason these modern elegant math descendants of the original GOLEM work are pragmatically testable at all is the accident I opened this post with: RSI showed up early, in modest and tractable form, riding on LLMs and MeTTa and minimal agent runtimes… giving us live self-modifying proto-AGI systems to hold the math theory against while the stakes are still instructive rather than existential. Both the math and the systems are getting better month by month, at a ridiculous and exciting speed. I’d rather debug goal-stability theory on an Omega hive rewriting its tool files than meet these questions for the first time in the context of an AGI uplifting itself to superintelligence…