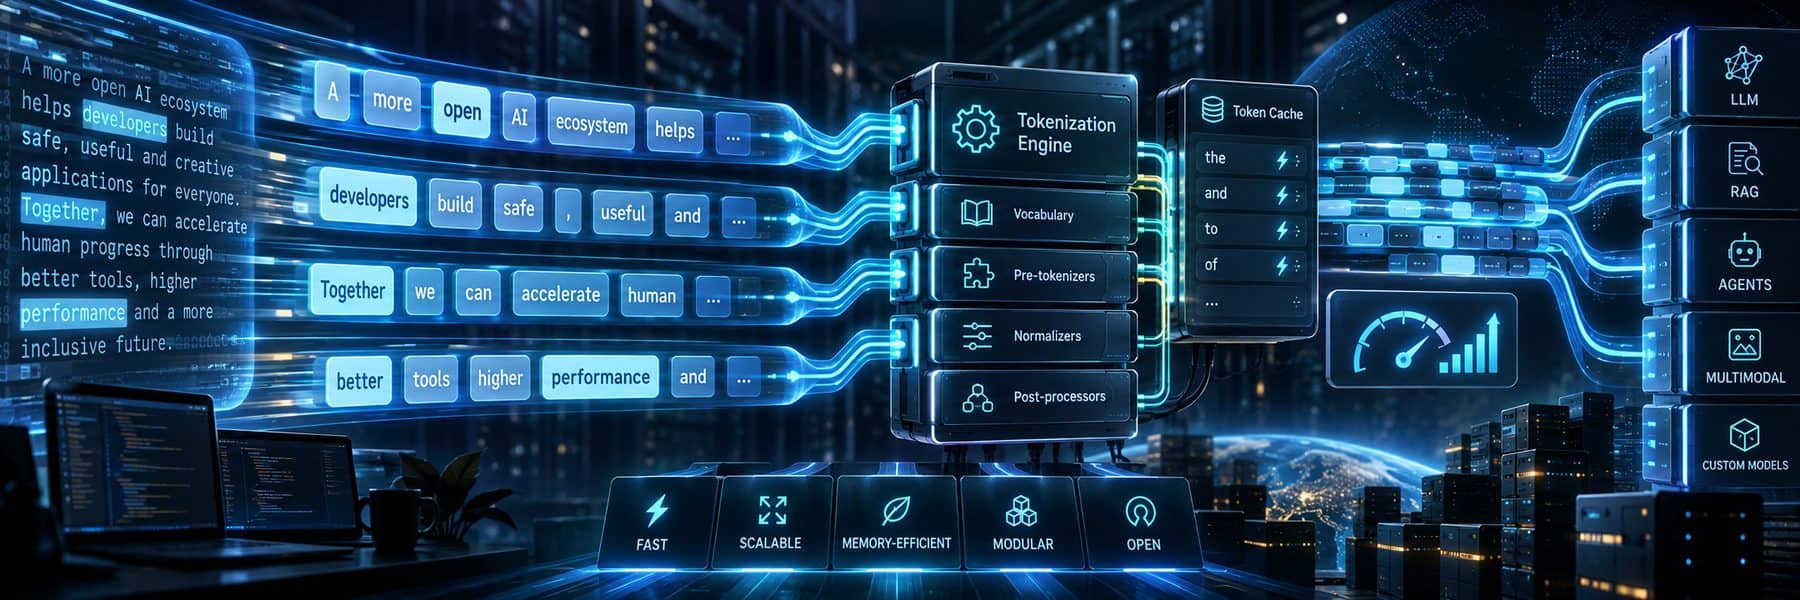
Hugging Face has previewed Tokenizers v1, a performance overhaul of the software that converts text into the numeric identifiers AI models read. Announced on September 21, the Rust release candidate preserves existing token IDs and interfaces.
In single-thread tests across ten model families on an Apple M4 Max, the team reports encoding speeds three to 30 times faster than version 0.23. Those measurements exclude the extra overhead introduced by Python bindings.
The improvements combine faster text splitting, cached results for repeated words, reusable working memory and parallel processing that avoids threads waiting on one shared lock. This follows a familiar route to reducing redundant AI computation: do less repeated work rather than alter the model’s input.
For developers seeking more efficient AI workflows, the distinction matters. Faster preparation can reduce the time GPUs spend waiting for CPUs to finish tokenization; it is not a claim that the model itself has become more capable.
The gains are not universal. Caching helps most when text repeats, and unsupported splitting patterns retain the older processing path. Hugging Face provides reproducible benchmarks, while further work remains before the final 1.0.0 release.