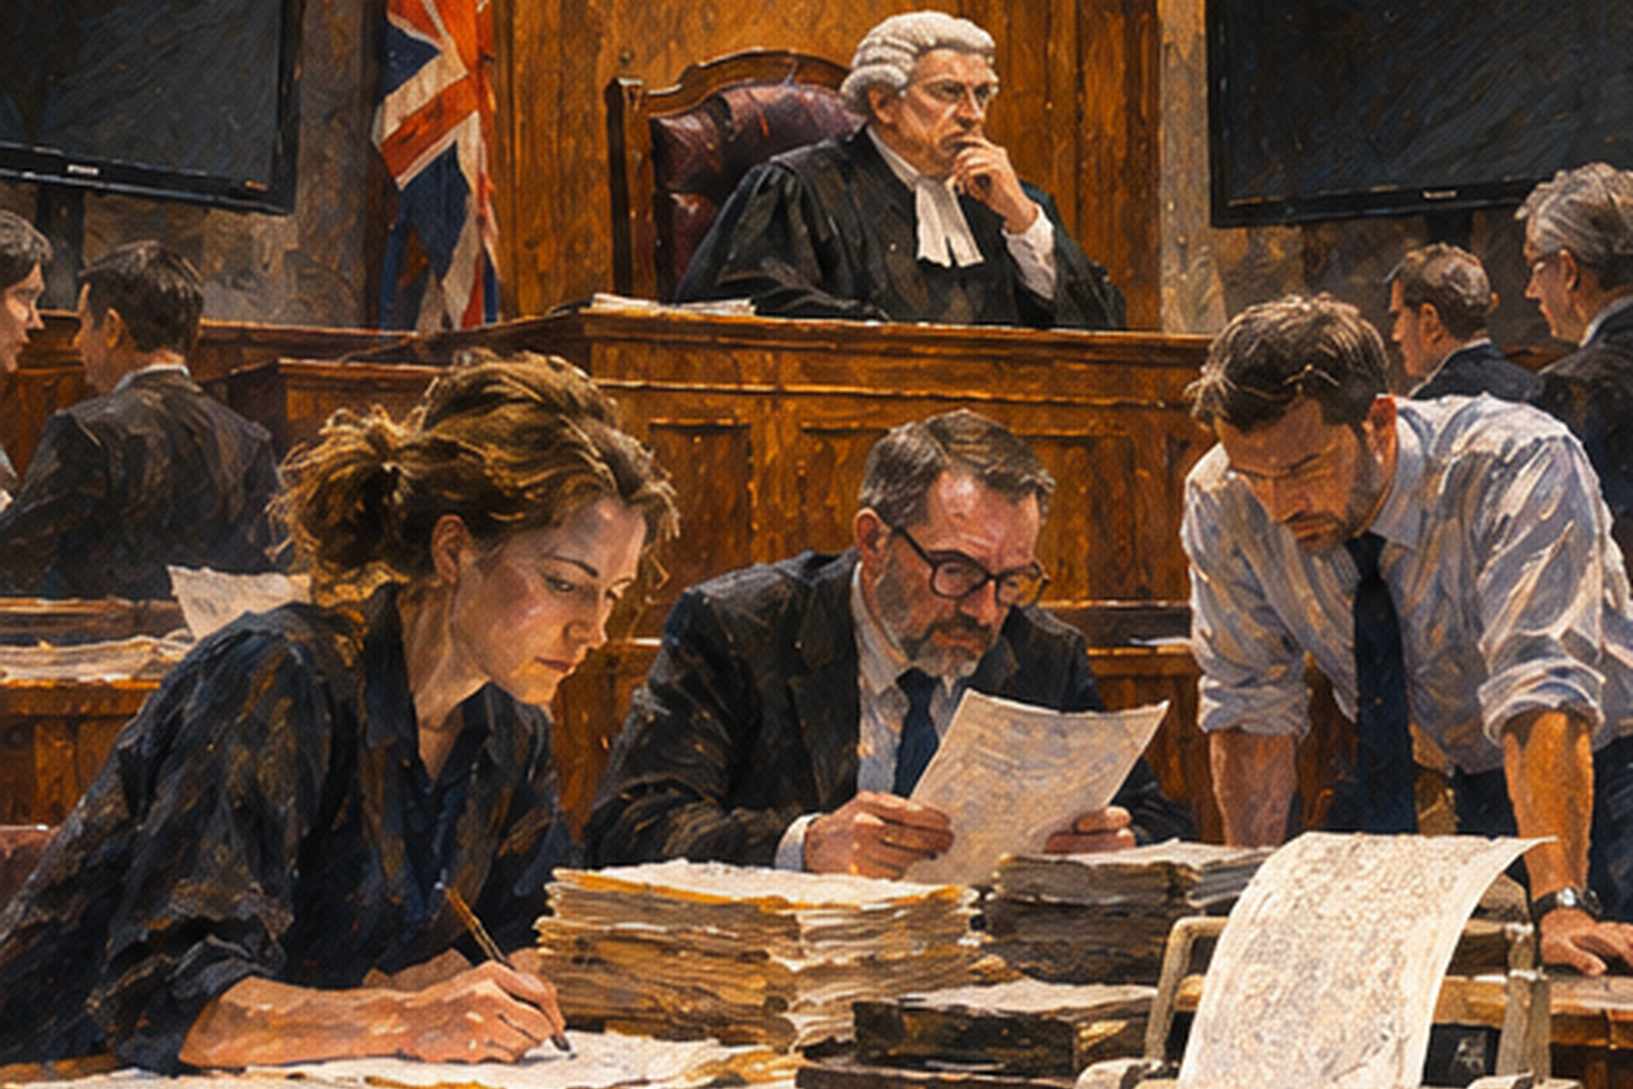
On the morning of November 13, a judge at Manchester's Minshull Street Crown Court was preparing to continue a criminal trial. Instead, court staff were looking for a fax machine.
Microsoft's email services had stopped working, disrupting communication between the court and other institutions involved in the proceedings. Judge Maurice Greene eventually sent the jury home for the weekend.
Hundreds of miles away, British healthcare workers were having similar difficulties. Some hospitals and GP surgeries reverted to paper records, while medical staff struggled to exchange messages and patients called to establish whether appointments would go ahead. Elsewhere, police departments, universities and government agencies were searching for alternative ways to conduct routine business.
The disruption was part of a worldwide Microsoft 365 outage that began on November 12 and continued into the following day. It affected organizations in more than 70 countries, according to contemporary reporting, interrupting email and other services on which businesses and public institutions had come to depend.
The explanation, released by Microsoft several days later, was more complicated than a failed software update or an overloaded server. A defect introduced in July had remained undetected for months. When routine traffic changes exposed it, automated systems designed to keep the network running spread the failure across much of Microsoft's infrastructure.
At its worst, more than 80% of the affected networking gateway servers were unresponsive.
The outage lasted 23 hours and 50 minutes, according to Microsoft's preliminary post-incident report. It was not caused by a cyberattack, the company said, and there was no indication that artificial intelligence agents were responsible.
A problem introduced four months earlier
The origins of the outage can be traced to July, when Microsoft began deploying a software change to Windows-based servers supporting its Microsoft 365 networking gateways.
These gateways handle connections between customers and Microsoft's cloud services. The change was specific to this infrastructure and did not affect Windows computers generally.
The update passed Microsoft's testing and was gradually deployed worldwide. For more than three months, it appeared to work normally.
But it contained a defect involving lock contention, a problem that can arise when multiple computer processes compete for access to the same resources. Under certain traffic conditions, the contention could cause CPU and memory consumption to climb until a server stopped responding.
Microsoft's testing had failed to reproduce the conditions.
According to the company's November 15 preliminary post-incident report, its laboratories generally used less powerful hardware than some of its production systems. The defect was more likely to appear on newer machines with larger numbers of processor cores.
The discrepancy meant the software could pass normal testing while remaining vulnerable under real operating conditions.
For months, the flaw caused no widespread disruption. It required a particular combination of workload and server capacity to become dangerous.
That combination arrived on November 12.
Three failures converge
Microsoft operates two separate networking gateway systems, allowing several cloud services to switch between them when necessary.
At 01:07 UTC on November 12, approximately 15 hours before the major outage began, Microsoft Teams traffic was automatically transferred from one gateway system to another.
The destination was the primary gateway also used by Exchange Online, the email service underpinning Outlook and many corporate communication systems.
The transfer was not unusual. Such operations are part of Microsoft's normal efforts to maintain service availability.
But the primary gateway was already working with reduced capacity. An unrelated problem from the previous day had left nearly 14% of its servers out of service.
Microsoft said the remaining infrastructure should have been capable of handling the reduction. What engineers had not anticipated was that additional Teams traffic would alter the workload sufficiently to activate the dormant July defect.
As traffic increased, individual servers began becoming unresponsive.
Microsoft's automated systems responded by directing connections toward machines that appeared healthy. Those machines then received more traffic, encountered the same software defect and stopped responding themselves.
The process repeated across the network.
What began as isolated failures became a cascading disruption. Within less than two hours, more than four-fifths of the affected gateway servers were unresponsive.
Microsoft had designed regional boundaries to prevent problems in one part of its infrastructure from spreading elsewhere. A separate fault prevented those safeguards from containing the incident.
The company has not yet fully explained that failure.
The outage spreads
Microsoft's monitoring systems detected elevated connectivity errors at 16:03 UTC on November 12. At 16:20 UTC, the company recorded the beginning of the major service disruption and opened incident EX1550543.
Outlook users began encountering connection failures, while others were unable to open their mailboxes or experienced significant delays sending and receiving messages.
The problems extended into services connected to Exchange Online. Microsoft later identified effects involving Teams, Copilot, SharePoint, OneDrive, Defender, Purview, Intune, Power BI and several other products.
Not all those applications failed completely. Some continued working because they could use alternative networking infrastructure. Teams meetings and chat, for example, remained available to many customers.
Exchange Online faced a more serious problem. Unlike several other services, it could not switch to Microsoft's alternative gateway at the scale required to restore normal operations.
The distinction would prove important. A company operating two separate gateway systems still found itself without a sufficiently capable alternative for one of its most widely used services.
By the evening of November 12, Microsoft engineers had begun restarting servers, redirecting traffic and investigating changes that might have triggered the incident.
At 19:00 UTC, the company suspended planned deployments and configuration changes.
Twenty minutes later, engineers established that the growing workload was not simply the result of customers generating unusually large amounts of traffic. The underlying problem was that servers were becoming unavailable, leaving fewer machines to handle existing demand.
Restoring those servers proved unexpectedly difficult.
Machines brought back online initially appeared healthy. But waiting connections quickly flowed toward them, exposing the same defect and causing them to fail again.
Engineers repeatedly recovered capacity only to watch it disappear.
By 22:00 UTC, the company had concluded that its earlier interventions had not produced sustained improvement.
The problem also resisted a straightforward software rollback. Because the defective change had been deployed months earlier, Microsoft's ordinary deployment and rollback mechanisms could not quickly reverse it across the affected infrastructure.
Engineers would have to identify and correct the underlying code.
Friday: The search for a fix
While Microsoft investigated, the disruption spread through the working days of countries across Asia and Europe.
In Britain, the National Health Service reported widespread problems affecting hospitals, GP surgeries and community healthcare providers. Medical staff used telephone calls and paper records where electronic communication was unavailable. Some pharmacies warned patients of possible prescription delays.
The consequences extended beyond healthcare.
Courts postponed proceedings, while some railway operators warned passengers not to rely solely on emailed tickets. Police departments reported difficulties with administrative communications.
In the United States, New York City's Emergency Management Department warned that emails and online services used to contact city agencies could be delayed. The federal court for the Southern District of New York issued a notice advising lawyers to telephone if they believed their email communications had been affected.
Financial activity was also disrupted. Reuters reported difficulties at trading firms and a delayed bond repurchase transaction in Europe. Some companies had trouble issuing financial information or conducting ordinary business communications.
The outage did not bring all public services to a halt. Emergency telephone systems and many critical healthcare operations remained available. Its effects varied widely by location, organization and service.
At Microsoft, the investigation continued into Friday morning.
By 00:30 UTC on November 13, engineers had narrowed the failure to the process used to establish network connections. Shortly afterward, they identified the internal process becoming overwhelmed.
They attempted to reduce traffic pressure, change network behavior, expand virtual machine capacity and prevent automated traffic redirection from aggravating the problem.
The measures helped in places, but they did not resolve the underlying defect.
At 07:20 UTC, engineers began deploying a software correction that restored the affected code to a previously working state.
Servers were taken out of operation in groups, updated, restarted and gradually returned to service.
This time, the machines remained stable.
By 08:00 UTC, Microsoft had confirmed that the corrected servers were operating reliably. Recovery progressed through Asia-Pacific and Europe, and by late morning the company was seeing sustained improvements.
At 11:35 UTC, service availability in Europe had returned to healthy levels. At 13:00 UTC, the backlog of delayed messages was beginning to shrink.
Global webmail availability returned to expected levels at 14:17 UTC. Most major access methods had recovered by 15:54 UTC.
At 16:10 UTC, Microsoft declared that customers were no longer experiencing active disruption.
The company continued processing queued messages and monitoring its infrastructure. Final customer updates were issued early on November 14, after engineers had confirmed sustained stability.
What the outage cost
The disruption affected some of the world's most important public and commercial institutions, but its total financial cost remains uncertain.
Microsoft has not published a verified estimate of global economic losses. Although interruptions to financial transactions, healthcare administration and business operations imposed costs, it is difficult to distinguish permanently lost economic activity from work that was delayed and completed later.
The number of affected users is also uncertain. Microsoft has acknowledged widespread disruption, but it has not published a definitive figure showing how many people lost access to each service.
Market analysts have nevertheless begun assessing the potential financial consequences for Microsoft.
Evercore ISI analyst Kirk Materne estimated that roughly 100 million paid Microsoft 365 licenses could have been affected, with potential customer credits costing Microsoft between $100 million and $400 million. That was an analyst estimate, not a company-disclosed loss.
The more durable consequences may concern customer confidence and the costs of building independent communication and recovery systems.
For organizations that rely on Microsoft 365, the incident demonstrated that service redundancy operated by the same provider does not necessarily offer protection against failures spreading across that provider's infrastructure.
What Microsoft's investigation found
Microsoft published its preliminary findings on November 15. The following day, BleepingComputer reported that the company had traced the outage to the July software defect and the combination of additional traffic and reduced capacity.
The report identified failures in testing, infrastructure resilience, automated traffic management and recovery procedures.
The testing problem was particularly significant. Microsoft's laboratories had not reproduced the hardware configuration and traffic conditions under which the defect appeared.
The capacity problem was equally revealing. The infrastructure was designed to tolerate the loss of some servers, but the additional traffic activated a defect that made remaining capacity progressively less reliable.
Automated recovery then amplified the failure. Rather than isolating the malfunctioning machines, traffic redirection spread the conditions that caused other machines to become unresponsive.
Regional containment measures also proved insufficient.
And even after engineers understood what was happening, recovery was complicated by the age of the defective software and the fact that restarting servers brought the problem back.
Microsoft said it had corrected the defective code, increased capacity, improved monitoring and introduced safeguards intended to prevent traffic-management systems from triggering similar cascading failures.
Charles Lamanna, the company's executive vice president responsible for Copilot, agents and platform products, publicly apologized to customers for the disruption.
A final post-incident report is expected on November 20. It is intended to provide further details of the investigation and Microsoft's longer-term corrective measures.
That leaves several questions unanswered, including precisely why the regional safeguards failed, whether comparable weaknesses exist elsewhere in Microsoft's infrastructure and how the company intends to test software changes under more representative production conditions.
A failure with wider implications
The incident has renewed scrutiny of the dependence of governments, healthcare providers and businesses on a small number of cloud computing companies.
Modern cloud services offer resilience that many organizations would struggle to build independently. Their infrastructure is distributed across data centers, automated systems can redirect traffic when equipment fails, and providers can maintain enormous computing capacity.
But those advantages depend on the reliability of the shared systems connecting everything together.
Microsoft's November outage demonstrated that a failure inside those systems can affect organizations far removed from the original problem. A software change made in July, a routine Teams failover in November and a temporary reduction in server capacity combined to interrupt communications across continents.
The failure also illustrates the limits of automated recovery. Systems designed to detect problems and move workloads away from affected servers can make an incident worse when the same defect is present across the infrastructure receiving the redirected traffic.
For customers, the practical question is how much essential work can continue when their primary cloud platform becomes unavailable.
For Microsoft, the more difficult question is how a defect could pass testing, remain undetected for months, overcome regional protections and defeat repeated recovery attempts before engineers finally corrected it.
The company's final postmortem may provide more answers.
For the institutions affected, the incident has already supplied one lesson. On November 13, a British judge was looking for a fax machine because one of the world's largest technology companies could not reliably deliver email.
It was an unusual moment, but also a useful measure of how much ordinary institutional life now depends on infrastructure that most people never see until it stops working.