Researchers at UCLA have built a hybrid detector that uses both a digital program and physical light to spot deepfake videos. The study is published in eLight. Usual detectors send each clip through a digital network one after another. That work uses many numerical operations, so time and energy rise with the number of videos. Those systems can also be misled by attacks crafted to make a fake look genuine.
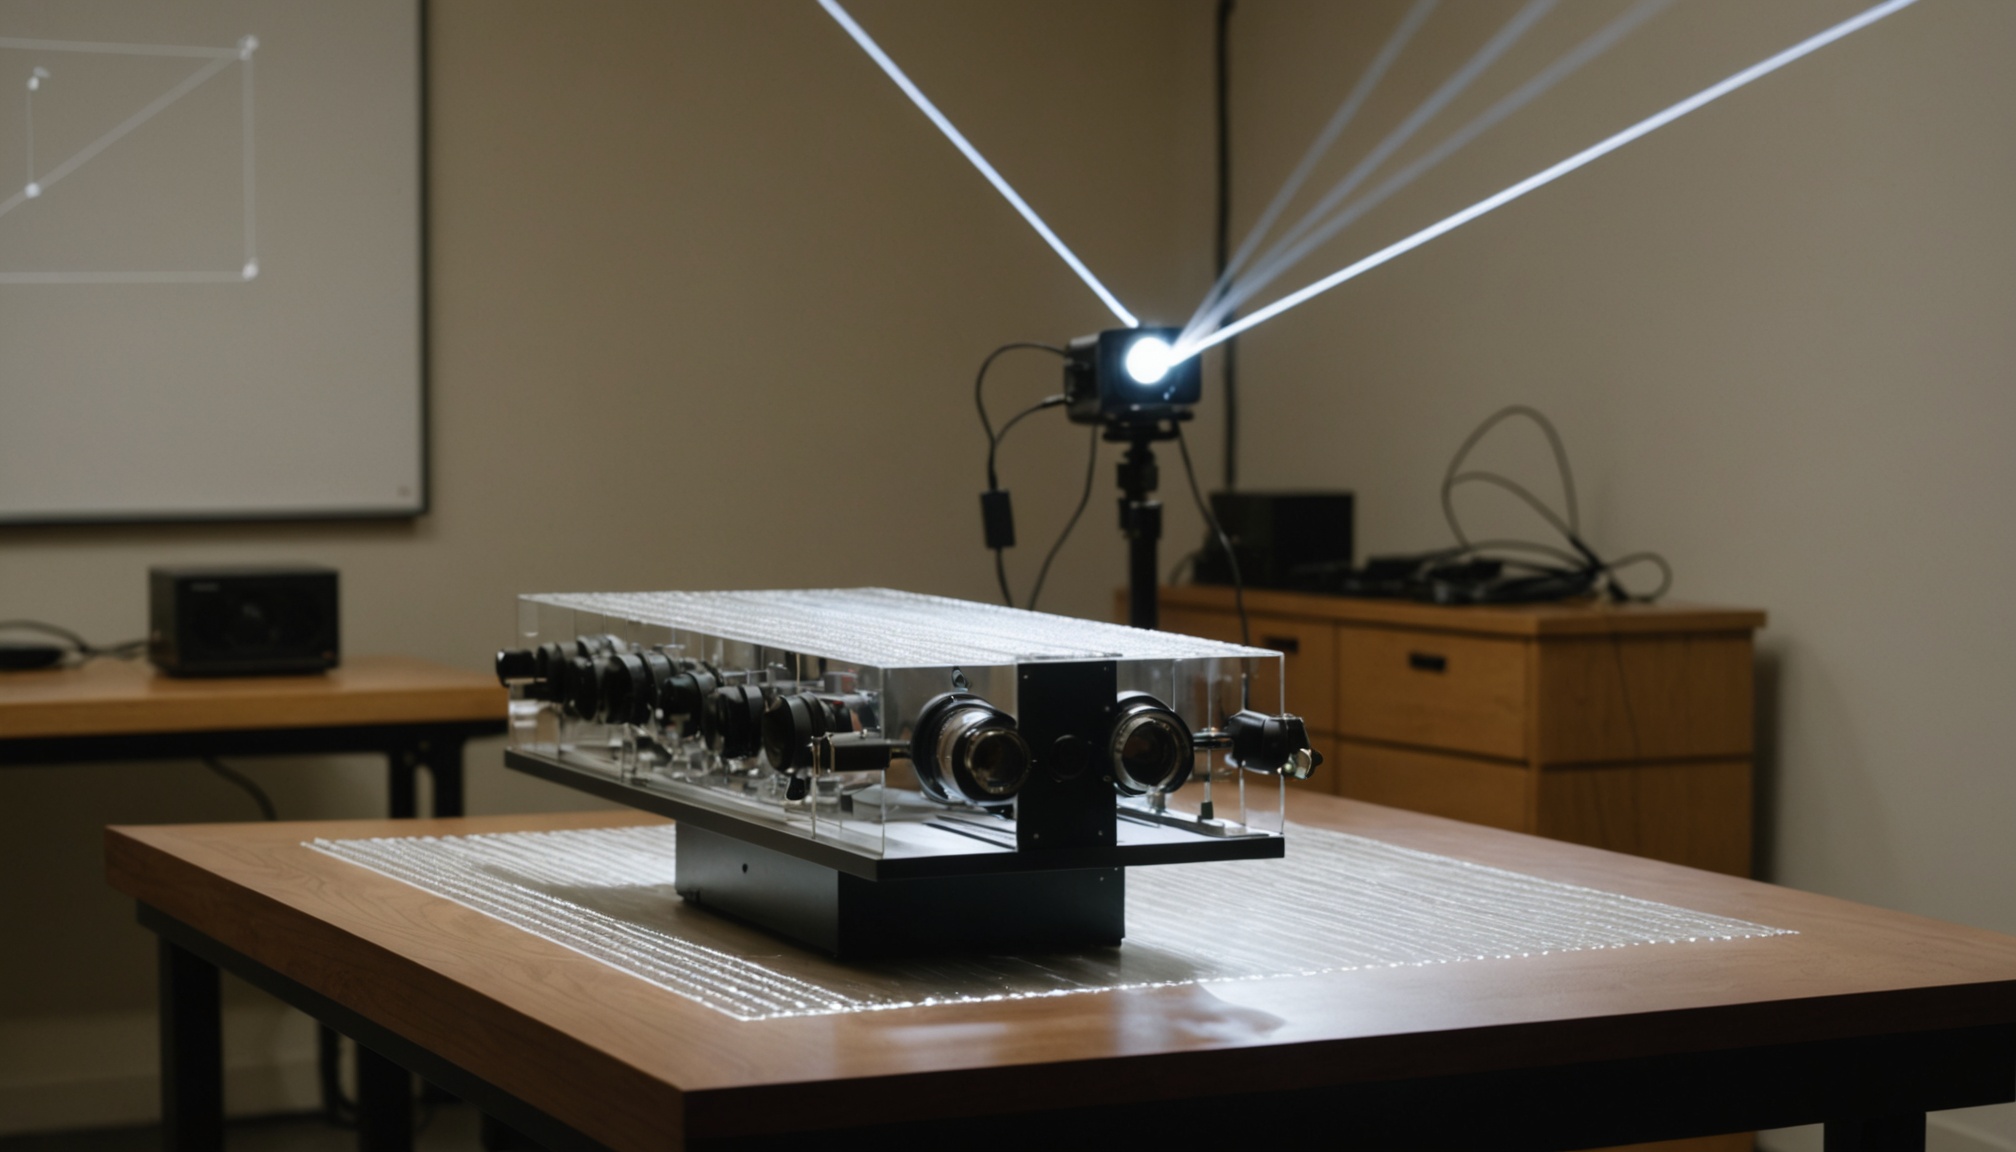
The UCLA design divides the task. A compact digital encoder first pulls spatial, color, and time cues from each video and turns them into a phase pattern. That pattern is written on a spatial light modulator, a programmable device that reshapes a light beam. The encoded wavefront, the light field after this step, then travels through a passive optical decoder in open air. Sensors at the output turn the arriving light into an authenticity score for each clip. Several videos can share the same optical path, so many clips can be judged in one pass.
Tests on standard and newer fakes
In a visible-light experiment, the apparatus examined 15 videos from Celeb-DF, a widely used face-swap test set, at the same time. Average accuracy was 97.79 percent. Sensitivity, the share of fakes correctly flagged, was 99.86 percent, so about 0.14 percent of fakes were missed. Specificity, the share of real videos correctly accepted, was 95.72 percent. With 18 videos per pass, accuracy was 96.13 percent. Two extra passive diffractive layers, thin surfaces that bend light by diffraction and need no electrical power during use, raised accuracy by about 6.8 percent on harder fakes. After a small amount of extra training, the same hardware reached 94.80 percent accuracy and 97.61 percent sensitivity on unseen clips from Google’s VEO-3 generator.
Because part of the inference is fixed in hardware, the detector is harder to copy and harder to fool with designed attacks. It also held up under noise, blur, JPEG compression, and small alignment errors. The authors describe it as a first filter: many videos would be screened in parallel by light, and only flagged clips would go to heavier digital models for a final check.