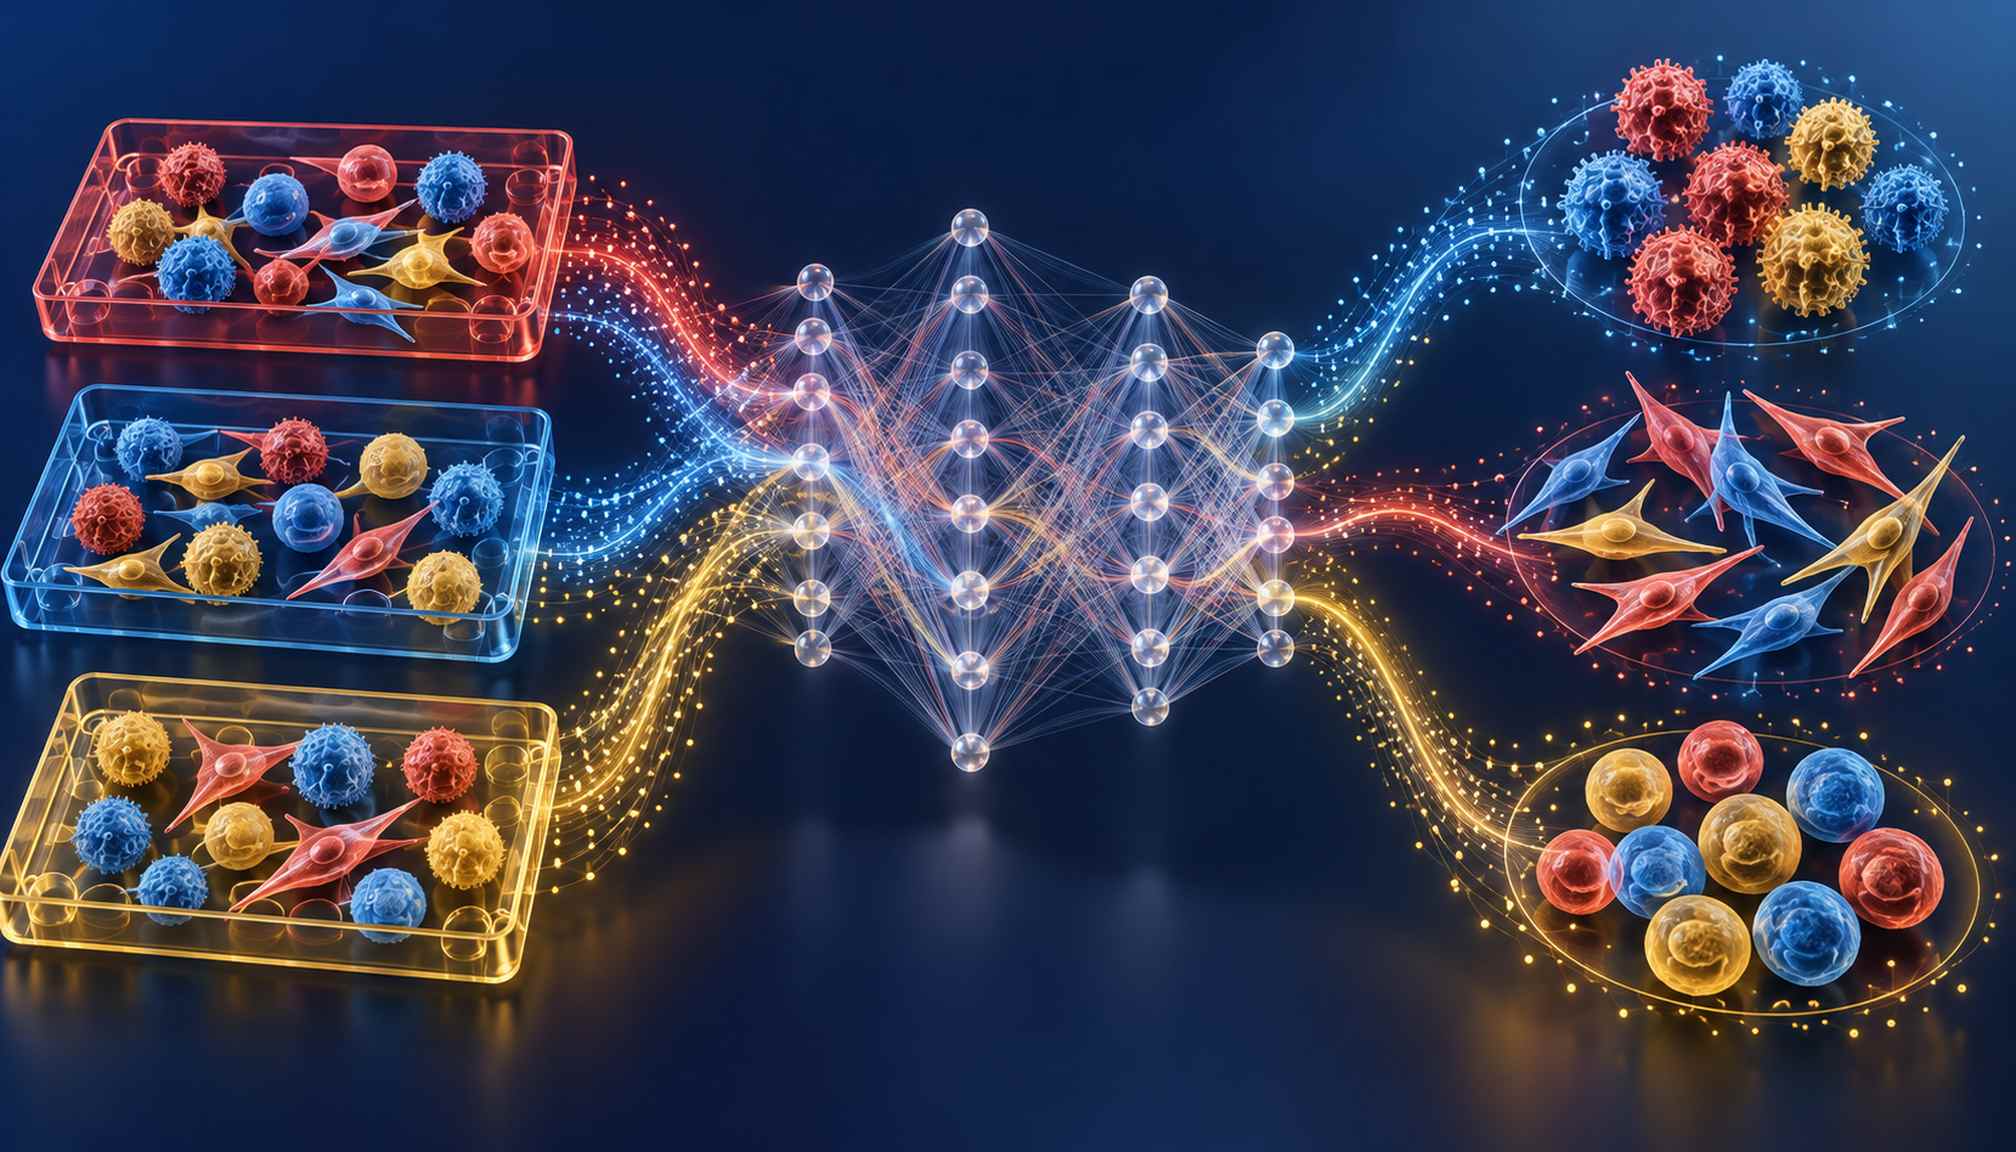
Biological datasets can disagree because experiments were conducted differently, even when the underlying biology is similar. Those technical differences, known as batch effects, can obscure the patterns researchers actually want to study.
Avraham Harrar and Uri Shaham address that problem in a study published October 15 in Bioinformatics. Their work introduces a structured formulation of batch correction alongside supervised and unsupervised approaches.
The supervised method uses known cell types to learn a shared representation across experimental batches. The unsupervised approach works without those labels, using an autoencoder and a discriminator to discourage its internal representation from retaining batch-specific information.
The researchers report better performance than comparison methods across multiple datasets. Their public code includes both approaches, example experiments and supporting mathematical proofs.
Reliable inputs matter as researchers develop tools for predicting how cells respond to unfamiliar drugs. Batch correction addresses an earlier step: making measurements from different experimental sources more comparable while preserving meaningful biological distinctions.
The contribution is a method for improving analysis, rather than a newly discovered treatment or disease mechanism. Its practical value will depend on how well those distinctions survive correction in additional datasets.