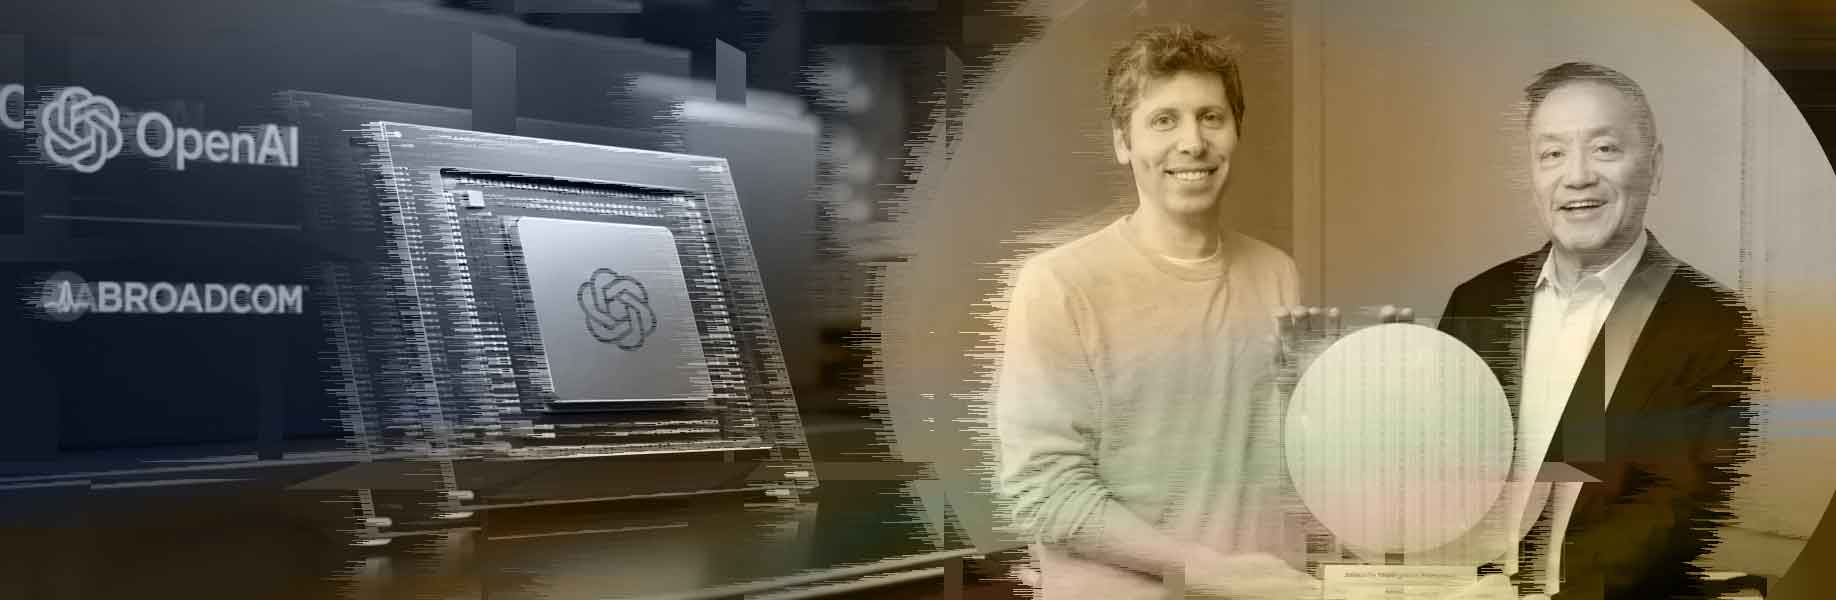
OpenAI and Broadcom have introduced Jalapeño, OpenAI’s first custom chip built specifically to handle the demands of large language models. The chip focuses on inference. Inference is the everyday operation of a finished model, where it quickly produces answers, text, or decisions when people or applications use it in real time. This is different from training, the much longer and more demanding earlier phase. Jalapeño is therefore optimized for fast, efficient use rather than for the initial learning stage. It was created from the ground up using OpenAI’s detailed knowledge of how these models operate in real products such as ChatGPT and future agent systems.
The design reduces unnecessary movement of data inside the chip and balances the main resources of computing power, memory, and connections between chips. Early laboratory tests indicate that Jalapeño achieves substantially better performance for each unit of energy used compared with today’s leading general-purpose chips, although final measurements are still being completed. Engineering samples are already running demanding workloads, including versions of advanced models, at the intended speed and power levels.
A rapid development timeline
Jalapeño reached the manufacturing stage in only nine months. This unusually short period for a complex custom chip, known as an ASIC, was supported by close work between the companies and by using OpenAI’s own models to assist parts of the design and testing process. Broadcom provided the silicon manufacturing and advanced networking technology, while Celestica contributed expertise in building the boards, racks, and full systems that will house many of the chips together.
This chip is the starting point of a multi-year platform intended for large-scale use beginning late in 2026. The overall aim is to increase the supply of computing power, lower costs, and improve reliability so that advanced AI becomes more affordable and dependable for students, developers, researchers, small businesses, and larger organizations. By controlling more layers of the technology from the chip level upward, OpenAI expects to create a cycle in which better hardware supports stronger models, which in turn enable more useful products and greater adoption.